I am Jiabo Zhan (詹佳博), an M.Eng. student in Computer Technology at Tsinghua University, Shenzhen International Graduate School, advised by Prof. Chun Yuan. I received my B.E. in Software Engineering from Beihang University in 2026, graduating 2nd out of 172 students (top 1.2%) with a GPA of 3.873/4.0.
My research focuses on computer vision, multimodal large language models (MLLMs), and reinforcement learning, with recent work on transparency-aware RGBA generation and editing, robust document parsing, and tool-augmented visual question answering. I am currently an algorithm intern in Tencent’s Weixin Group (WXG), Technology Architecture Department, working on multimodal training data, supervised fine-tuning, and evaluation.

🔥 News
- 2026.09: Started my M.Eng. studies in Computer Technology at Tsinghua University, Shenzhen International Graduate School, advised by Prof. Chun Yuan.
- 2026.09: WeVisDoc was released as a technical report on robust end-to-end document parsing, with open-source code and 2B/4B model weights.
- 2026.08: PaDoc was released with open-source code and model weights.
- 2026.08: 🎉 OmniAlpha was accepted to ACM Multimedia 2026 (ACM MM 2026) as an Oral Presentation!
- 2026.07: Joined Tencent WXG’s Technology Architecture Department as an algorithm intern.
- 2026.04: OmniAlpha was substantially revised with multi-task reinforcement learning for transparency-aware generation.
- 2025.11: OmniAlpha was released with open-source code and model weights.
- 2025.07: AlphaVAE was released with open-source code, data, and models.
📄 Technical Reports

WeVisDoc: From Coverage to Capability for Robust End-to-End Document Parsing
Hao Yu*, Kang Liu*, Linnan Zhao*, Jiabo Zhan*, Chong Sun, Chen Li, Jing Lyu
* Equal contribution (co-first authors). Technical Report, 2026.
Research period: Jun. 2026 – Sep. 2026.
Report / PDF / Project / Code / Model (2B) / Model (4B)
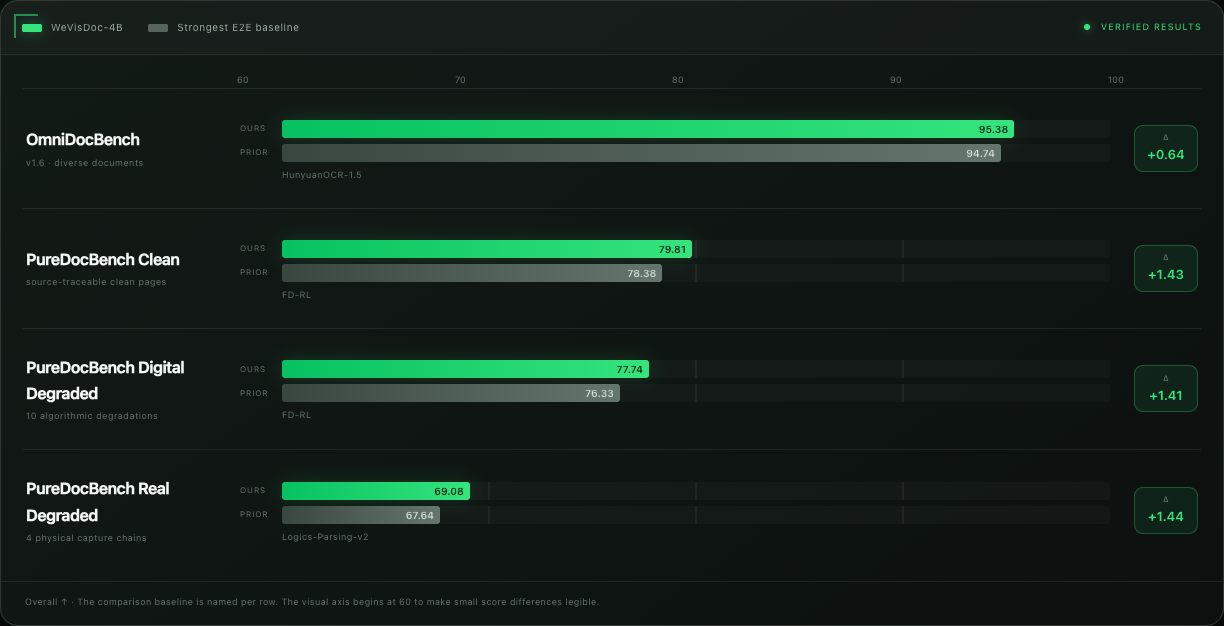
- A two-stage data-centric framework that expands document coverage, then uses residual-error diagnostics to guide targeted data construction and training-budget allocation for robust end-to-end parsing.
- WeVisDoc-4B achieves an Overall score of 95.38 on OmniDocBench v1.6 and a mean Overall score of 75.54 across the three PureDocBench tracks, ranking first among the compared end-to-end parsers in all four settings.
- Contribution: Collected and annotated handwriting, exam-paper, and textbook data; deduplicated samples by hash and filtered corrupt or unreadable documents. Combined candidate annotations from MinerU2.5-Pro and PaddleOCR-VL with MLLM review and manual region-level reannotation to produce consistent training ground truth.
- Built document degradation and augmentation pipelines covering wrinkles, bending, rotation, real-scene synthesis, and blur, while preserving image–annotation consistency and content readability.
📝 Publications
OmniAlpha: Aligning Transparency-Aware Generation via Multi-Task Unified Reinforcement Learning
Hao Yu*, Jinglin Wang*, Jiabo Zhan*, Rui Chen, Zile Wang, Huaisong Zhang, Hongyu Li, Xinrui Chen, Yongxian Wei, Chun Yuan
* Equal contribution. ACM Multimedia 2026. ORAL PRESENTATION
Research period: Jan. 2026 – Apr. 2026.
Paper / PDF / Code / Model / Scholar
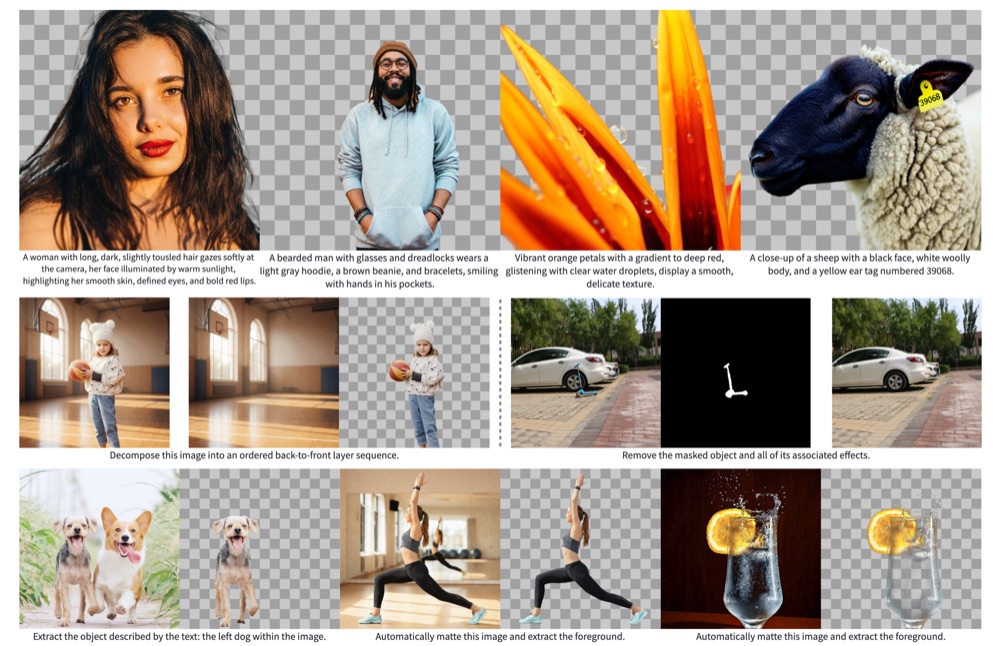
- A unified RGBA generation and editing framework for five transparency-aware tasks: text-to-RGBA generation, object removal, automatic matting, referring matting, and layer decomposition. The model achieves state-of-the-art or near-state-of-the-art results across all five tasks.
- Contribution: As a co-first author, was primarily responsible for multi-task training-data schema design, sample construction, data cleaning, and evaluation-code development. Participated in multi-task SFT cold-start training and GRPO-style RL post-training, with a focus on reward design, cross-task evaluation, and training stability.
PaDoc: Layout-Grounded Parallel Decoding for Document Parsing
Hao Yu*, Jiabo Zhan*, Kang Liu, Linnan Zhao, Dongxu Yue, Rui Chen, Jinglin Wang, Chong Sun, Chen Li, Jing Lyu, Chun Yuan
* Equal contribution.
Paper / PDF / Code / Model / Scholar
- A layout-grounded parser that branches regional content from shared full-page prefixes, improving throughput by 67.4–118% over same-backbone sequential decoding while retaining top-tier parsing quality.
Zile Wang, Hao Yu, Jiabo Zhan, Chun Yuan
Paper / PDF / Code / Model / Scholar
- An alpha-aware VAE for end-to-end RGBA reconstruction and transparent image generation, accompanied by the ALPHA evaluation benchmark.
- Contribution: Curated and governed 8,124 high-quality RGBA training samples and helped design the benchmark, evaluation code, and LoRA data iteration workflow.
🎓 Education
Research focus: computer vision, multimodal large language models, and reinforcement learning.
Ranked 2/172 (top 1.2%) and admitted to Tsinghua University for graduate study through recommendation, exempt from the national entrance examination.
💼 Internships
- Built and governed Parsing/VQA data for WeVisDoc document understanding: maintained approximately 9 million VQA examples, added approximately 1.5 million examples, and curated around 30,000 pages of long-tail documents such as handwritten notes and exam papers through deduplication, reannotation, and training-data delivery.
- Constructed mixed Direct/CoT supervision, ran two-stage SFT and cross-task evaluation, analyzed shifts in model capabilities, and optimized sampling ratios across data sources.
- Built 57,132 Direct/tool-assisted QA examples involving Zoom/Crop and Python through teacher-model generation, real tool execution, and automated review. Completed tool-augmented SFT of Qwen3-VL-4B-Instruct, improving accuracy from 40.6% to 45.9% (+5.3 percentage points) on the 1,000-question CharXiv-RQ validation set under the same Direct protocol.
- Developed a locally deployable open-source VLM solution for driving behaviors such as crossing solid lane markings and overtaking. Uniformly sampled 16 frames from rosbag videos as 2D multi-frame inputs and fine-tuned Qwen3-VL-8B-Instruct with manually reviewed ground truth, covering input modeling, supervision-data construction, and SFT.
- Improved model accuracy from 59% to 70% (+11 percentage points); the Gemini 2.5 Pro baseline achieved 80%. Replaced the original API workflow, priced at approximately US$10 per million tokens, with local GPU deployment and inference.
🏆 Honors & Awards
- National Scholarship, 2022–2023 and 2023–2024 academic years.
- Outstanding Student and Outstanding Communist Youth League Member at Beihang University, 2022–2023, 2023–2024, and 2024–2025 academic years.
- Samsung Scholarship, 2024–2025; First Prize in Beijing, Chinese Mathematics Competitions for College Students.
- More than ten additional university-level scholarships at Beihang University.
🛠 Skills
Models & Training
VLM, VAE, and DiT training and evaluation; SFT and GRPO; knowledge of DPO and PPO.
Data & Evaluation
Training-data construction, cleaning and governance, benchmark and evaluation-code development, offline evaluation, and error analysis.
Multimodal Understanding
Visual grounding, OCR, layout analysis, key information extraction, and image-text-structured signal modeling.
Engineering
Python, PyTorch, C/C++, and Java; multimodal pipeline engineering and product deployment.
Languages
Chinese (native); English (CET-4: 662, CET-6: 633), including academic reading and spoken communication.
Service
Staff member of the School of Software Student Union's Academic Center; teaching assistant for College English and Compiler Technology; 250 hours of volunteering in Beijing.